Local agents13 Nov 2026NEW
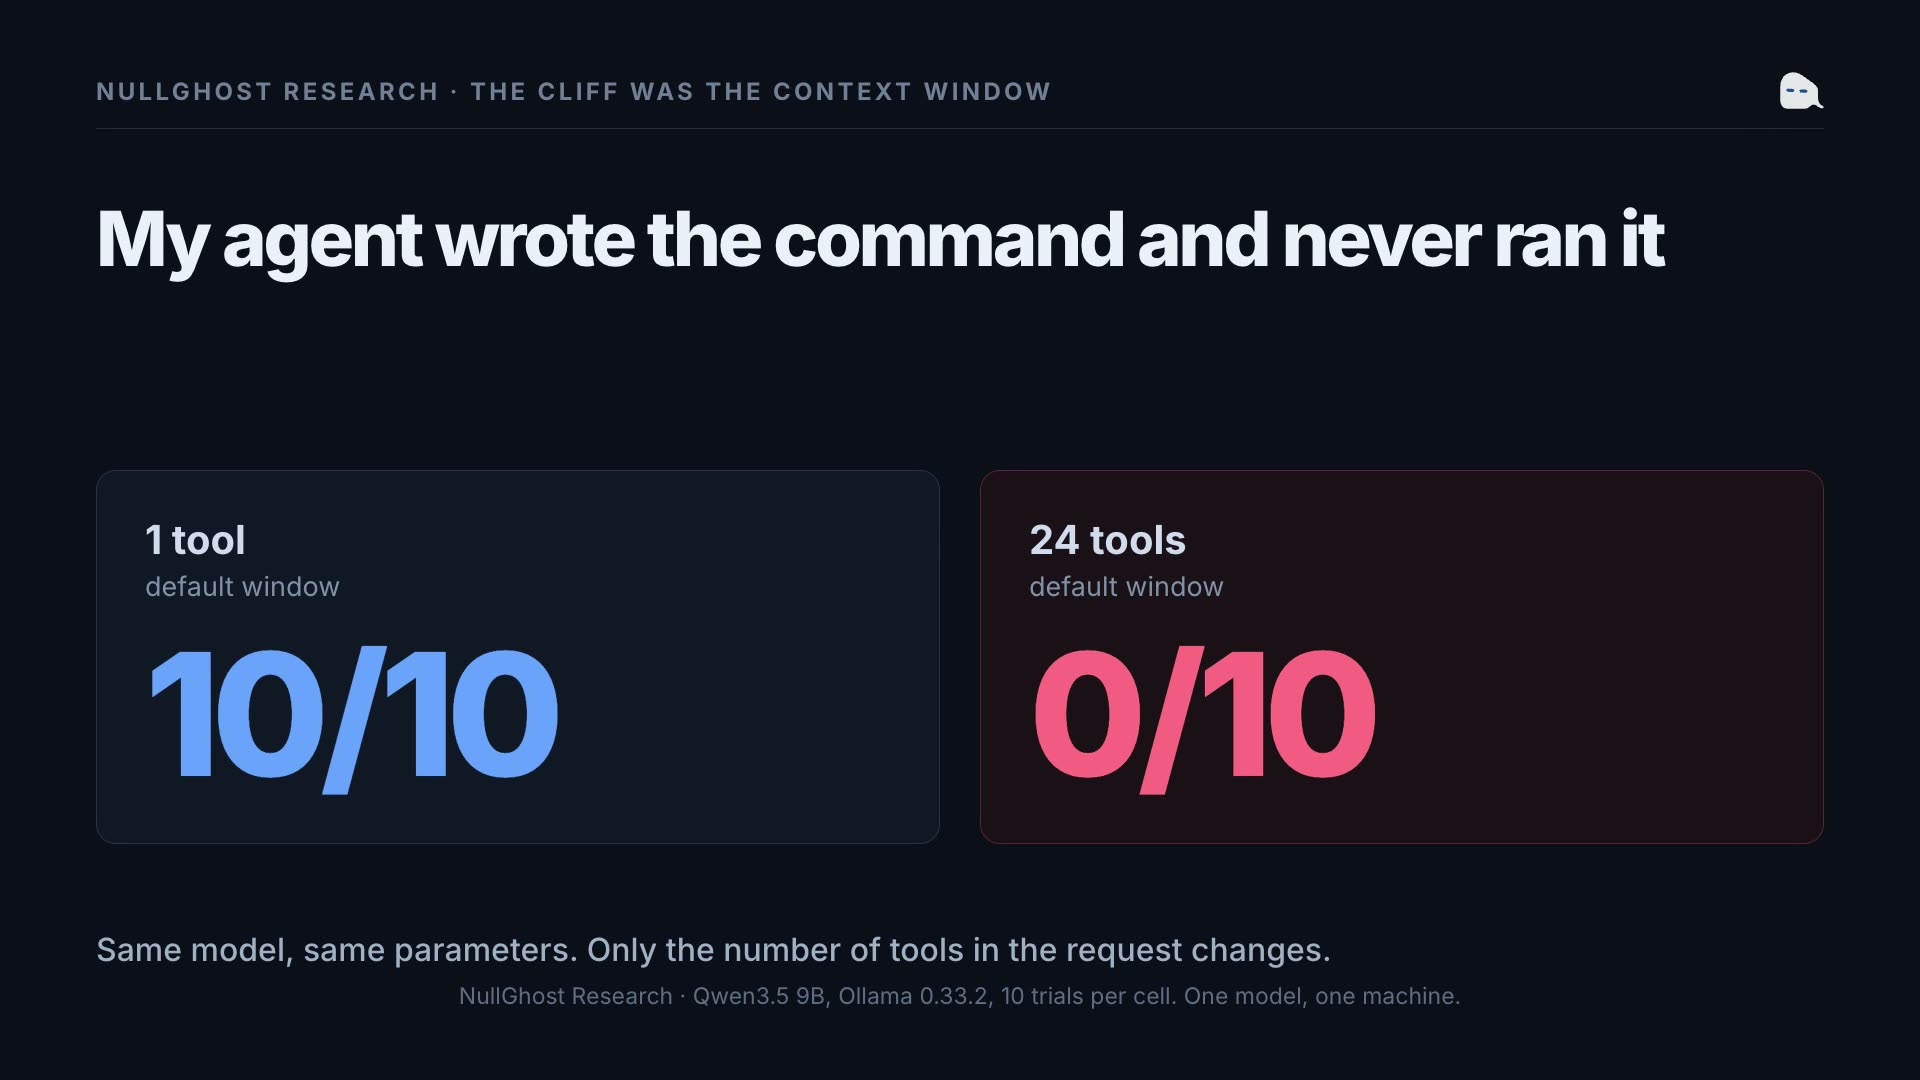
The Cliff Was the Context Window
A small model stopped calling its tools. It looked like a tool-count limit; it was a silent prompt truncation.
A verification layer between an agent’s decision and its action. We examine the pattern through TypeSafe AI / Jev.
A valid output does not guarantee a correct decision. If verification fails, the action should stop or be escalated.
The pattern combines a bounded set of decisions, confidence thresholds measured against known cases, and blocking on errors. It complements authorization and scope boundaries: a semantic evaluation must not override them. The repository includes a standalone code illustration.
Evaluation based on public sources, without production deployment or vendor endorsement. Vendor cost, latency and accuracy claims require independent reproduction. The code example does not constitute a Jev integration in Kirux.
A small model stopped calling its tools. It looked like a tool-count limit; it was a silent prompt truncation.
How xAI, OpenAI, Anthropic, Microsoft and Google govern their autonomous agents today, and who answers for what they do.
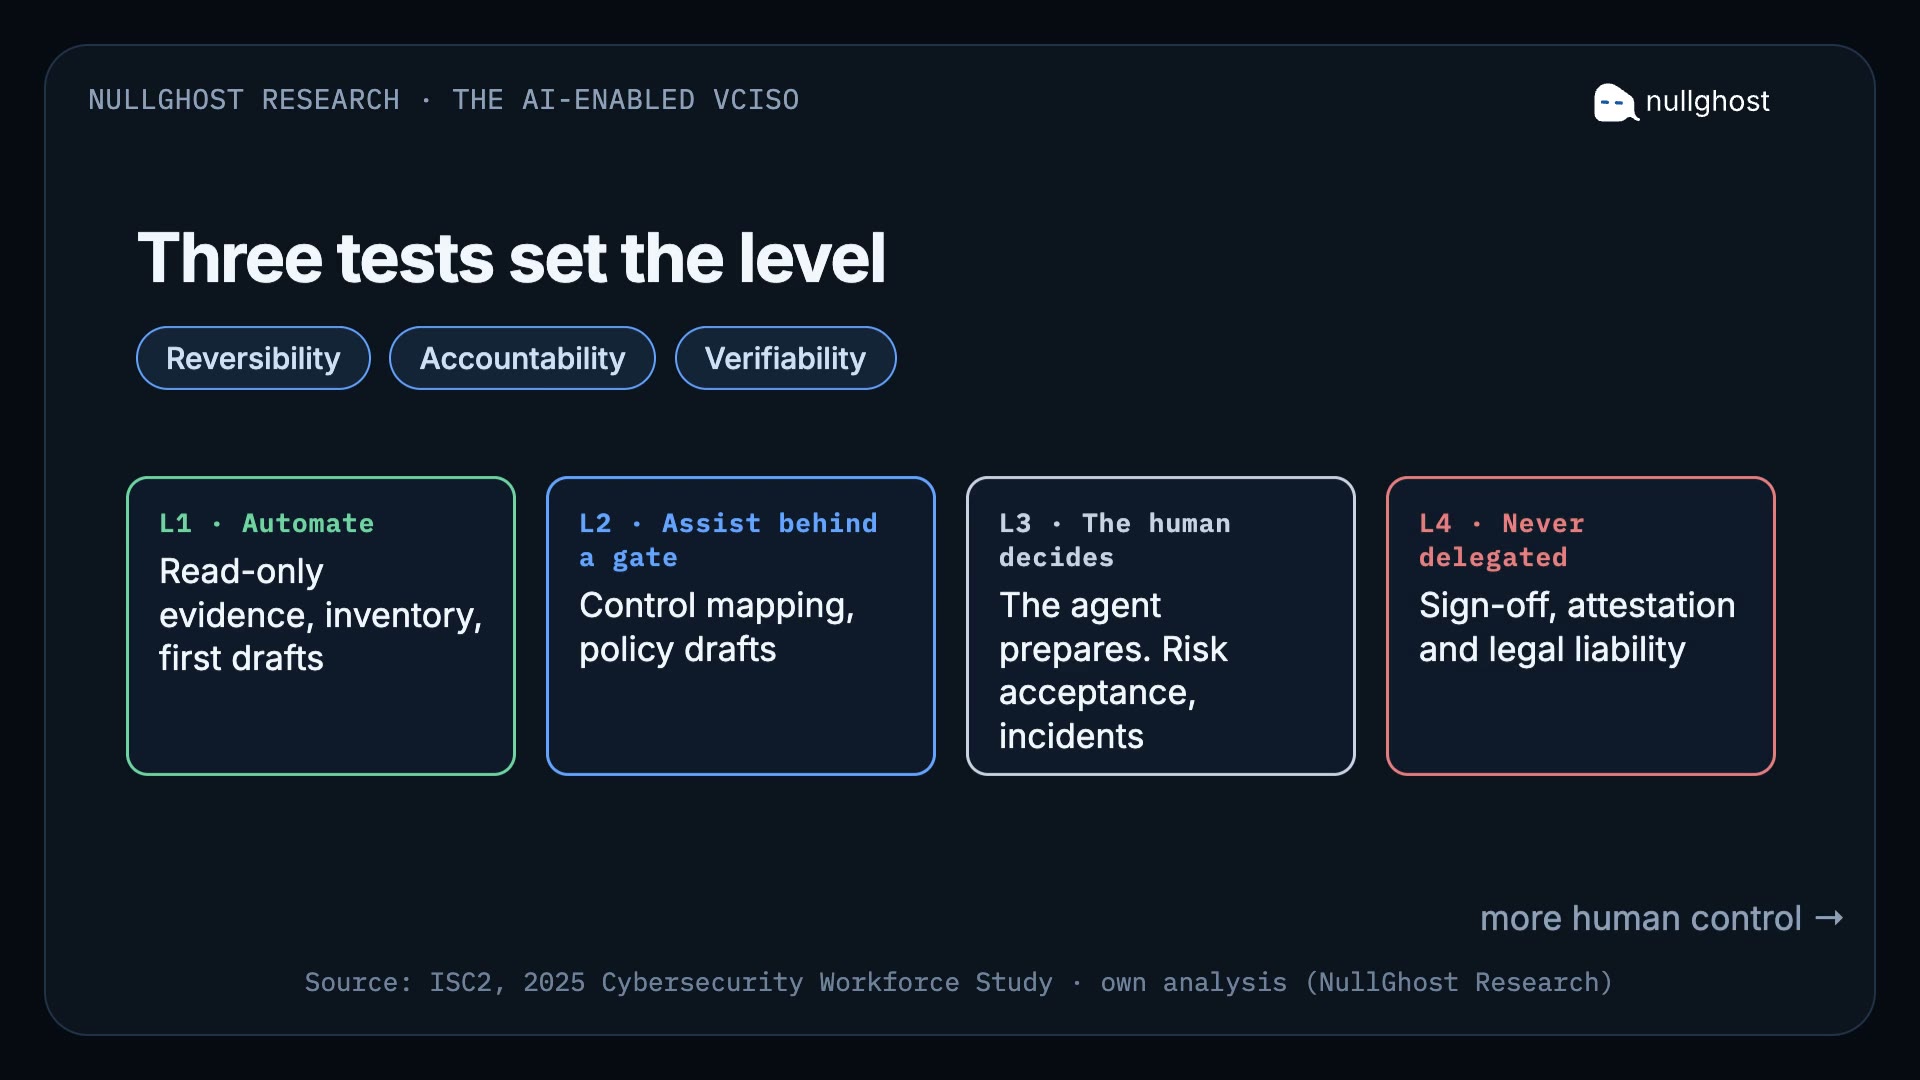
What gets delegated to an agent, what gets verified and what cannot be delegated. A four-level ladder and a measurement protocol, with explicit sources and limits.