Autonomous agentsOct 26, 2026
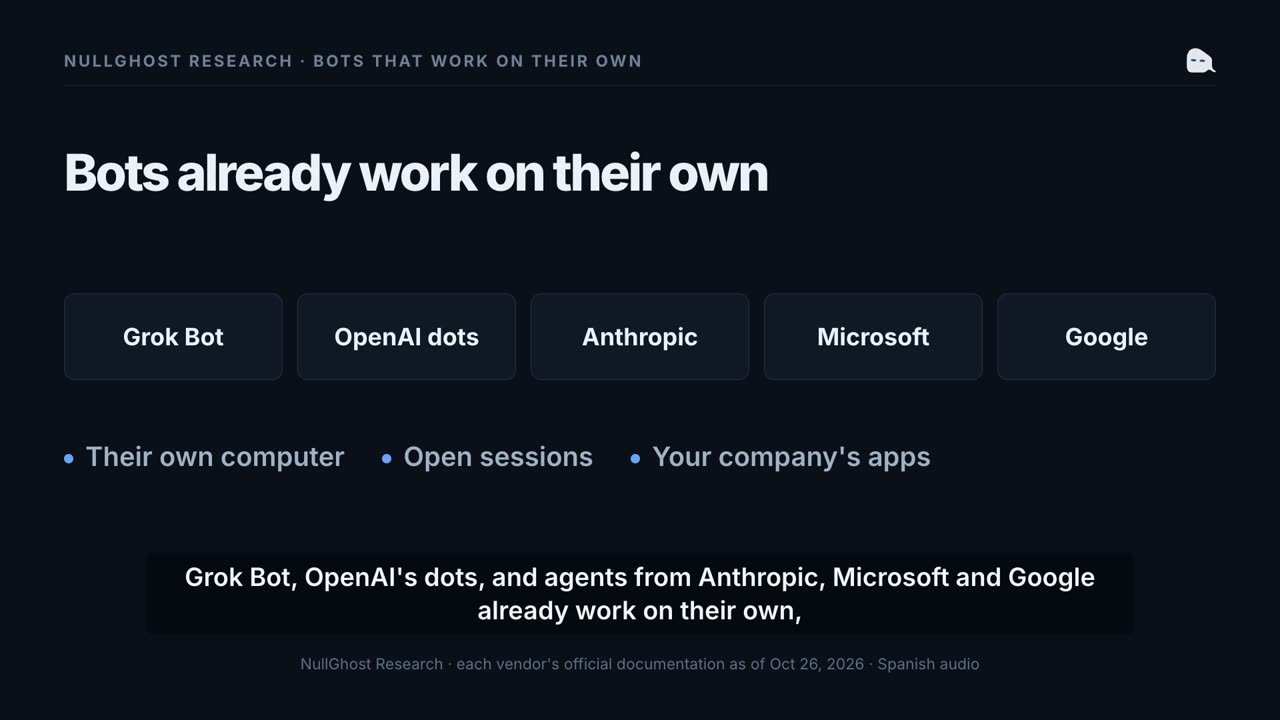
Bots that work on their own
How xAI, OpenAI, Anthropic, Microsoft and Google govern their autonomous agents today, and who answers for what they do.
A small model stopped calling its tools. It looked like a tool-count limit; it was a silent prompt truncation.
Before concluding that a small model cannot use tools, check how many tokens it actually received.
A 9.7B model passed the one-tool test and called none of an agent’s 24 tools. The request weighed 14,095 tokens and the server, with its default 4,096 window, cut it to about 2,050 without warning, right where the tool schemas sit. With the window at 32,768, the same request produced a correct call in 10 of 10 trials, and the sweep from 1 to 24 tools was flat. Lowering the temperature changed nothing. A synthetic control with a single tool, padding the prompt to the size of 24, fails and succeeds exactly where the 24-tool request does: what matters is prompt size against the window, not the number of tools.
The agent’s request was captured with a local proxy, replayed ten times per condition against the same model, and checked with a synthetic control that separates tool count from prompt size. It is one model (Qwen3.5 9B), one server version (Ollama 0.33.2), one machine and one task; with ten trials, 0 of 10 and 10 of 10 are distinguishable, small differences are not. The original server configuration on the day of the failure was not recorded. An earlier version of this work described a tool-count cliff; that claim was wrong and these measurements replace it.
How xAI, OpenAI, Anthropic, Microsoft and Google govern their autonomous agents today, and who answers for what they do.
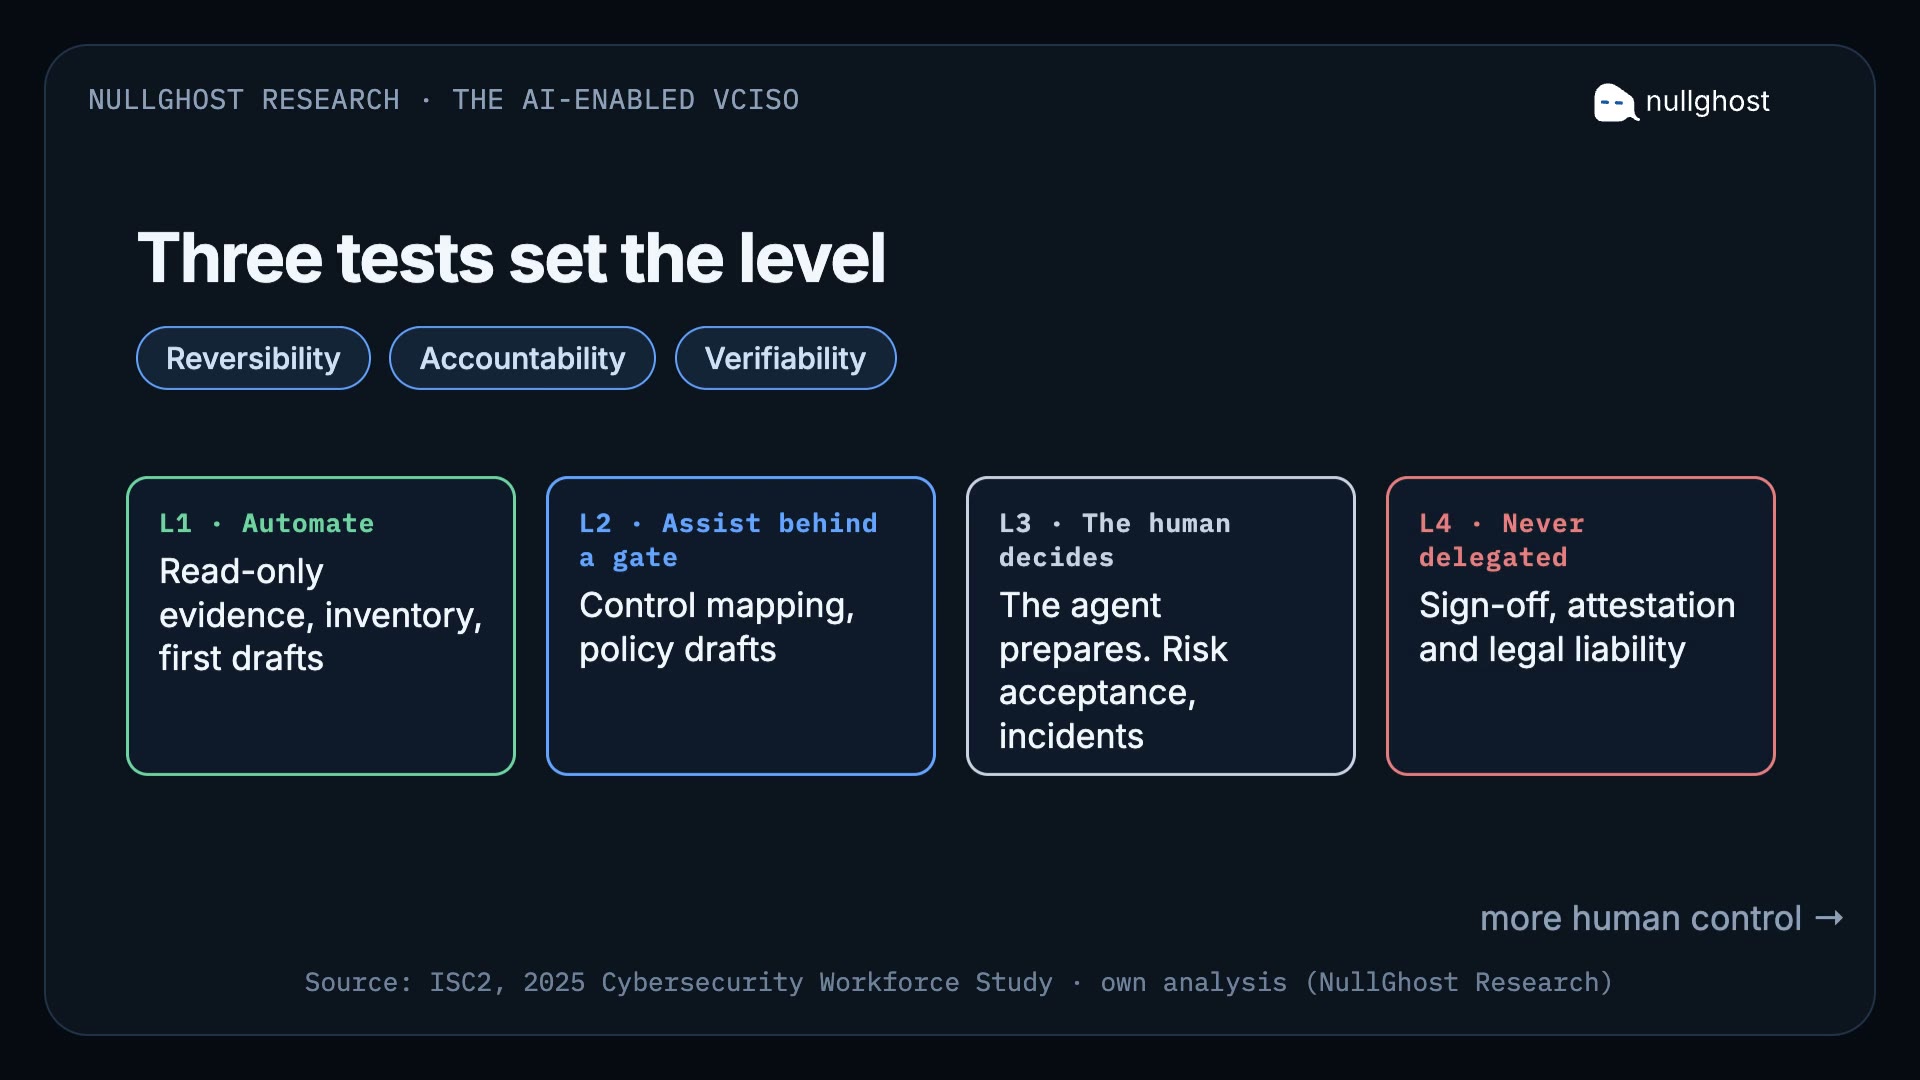
What gets delegated to an agent, what gets verified and what cannot be delegated. A four-level ladder and a measurement protocol, with explicit sources and limits.
What has been measured, what has been projected and what has been legislated. Each source is tagged by verification level and no date is promised.